SliverWorkspace


A lightweight DAG engine built on declarative I/O, shell commands and variable interpolation

SliverWorkspace 2.7.844644 released: New drag-and-drop component-based report designer supporting 12 common chart types and data tables, completing the end-to-end loop of pipeline design, input and output
  • Brand-new login page, fresh theme colors, software notifications, user feedback and more.
  • Sample input data form designer: turn pipeline input variables into forms
  • Enhanced guide mode: select existing files and complete an analysis in just 4 clicks; file uploads support resumable uploads.
  • File preview: analysis output files in tsv/csv/vcf/vcf.gz/bam/pdf and many image formats can be previewed directly, and viewed alongside IGV (Integrative Genomics Viewer).
  • Professional pipeline code editor: variable input/output hints, find and replace, full-screen display
  • Real-time task output logs
  • Redesigned file manager with greatly improved performance
  • Pipeline inputs/outputs support the file wildcards * and ?
  • Analysis output files (web pages, images, PDF documents) open directly in the browser without download
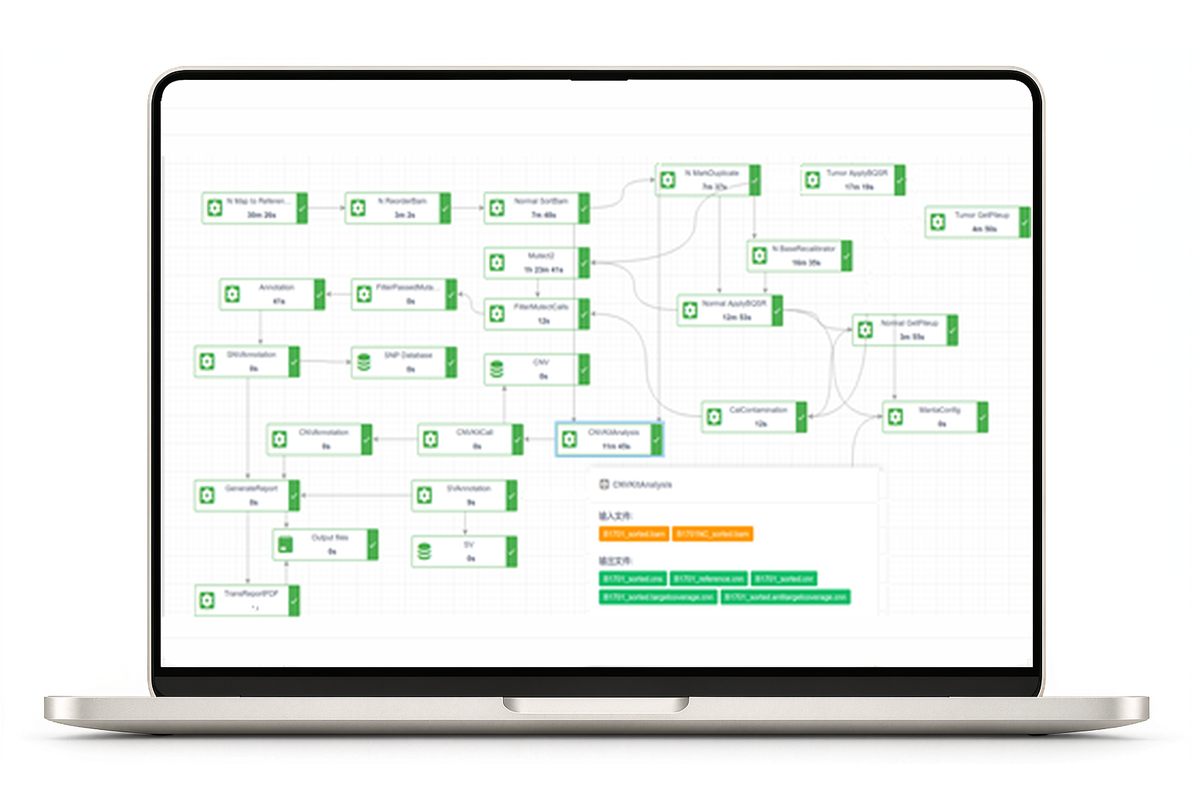
  • Shell-based graphical pipeline designer; supports WDL, Snakemake and Nextflow workflows
  • Real-time graphical pipeline run control and timing statistics
  • Smooth scaling from a single server to TORQUE/PBS or Slurm clusters
  • Analysis results stored in a database with massive storage and backup
  • Flexible multi-account, multi-role configuration and business data authorization for easy team collaboration
  • Analysis server node performance monitoring (CPU, memory, I/O, network) with alerting
The SliverWorkspace pipeline designer interface
...

A DAG engine built on declarative I/O, shell commands and variable interpolation

A ${variable} interpolation engine on a shell-syntax foundation, compatible with the higher-level extensions of WDL, Snakemake and Nextflow workflows.
The deeper meaning of an I/O declaration: an input/output declaration is not just file matching — it defines the container mount boundary. Local directories are mounted into the Docker container exactly as needed (e.g. ${data} mounted read-only, ${result} mounted read-write), which narrows each task's read/write scope on the host and reduces the risk of container escape or accidental writes to the host. This is why the designer requires nodes to declare I/O before writing commands: the declaration is the allow-list.

Learn More
...
...
...

Real-time monitoring of the analysis process, run-time statistics and flexible process control

While running, analysis status is displayed in real time and run time is tracked; you can stop the analysis at any time and resume from where the pipeline was stopped or failed.

Learn More
...

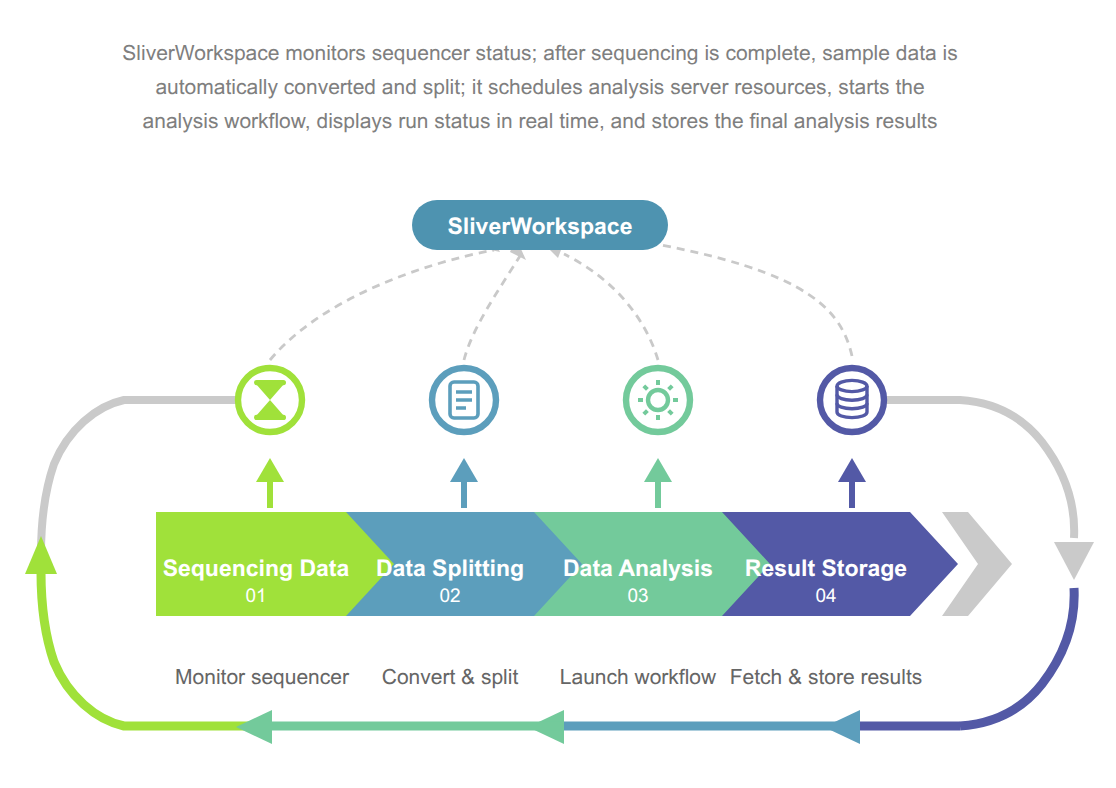
Fully automated from sequencer to final analysis results/reports

Fully automated analysis control built on sample information, server resource scheduling and flexibly designed pipelines. Runs 24/7, saving manpower and delivering higher efficiency at lower cost.

Learn More
...
...

Analysis results stored in the database in standard data formats, enabling rapid data accumulation for later data mining and regression analysis

Users can define custom output data formats; after analysis completes, results are stored in the database, providing massive storage capacity so users can rapidly accumulate data for subsequent data mining and regression analysis.

Learn More
...

Products & Services

Personal & Research

Community Edition

Graphical development and debugging of analysis pipelines, small-scale analysis.

Free
  • No feature limits
  • Up to 1 user
  • Up to 2 analysis nodes
Team Application

Commercial / Education Edition

Graphical design, development, debugging, deployment and automated execution.

  • No feature limits
  • Multiple accounts
  • Multiple analysis nodes
  • Non-profit education/research institutions can register with an institutional email and apply for a free license
Large-scale Deployment

Enterprise Edition

Large-scale deployment from multiple compute nodes to clusters and supercomputers.

  • Team collaboration, multi-account multi-role
  • Access control scoped to business data
  • Source Code License: source code available for custom development (all features except the graphical designer; existing pipelines can be imported)

About Us

The author of SliverWorkspace comes from a leading Chinese NGS company. Over several years, against the backdrop of rapid industry growth, trial and error in real-world work solved many problems and drove the company's technical progress. Some of these practices, developed with mainstream front-end and back-end IT technologies, have been given back to the community to advance the industry.

More Product Advantages

Using this product brings many more advantages: significant efficiency gains along with greatly reduced operations and maintenance costs. An excellent software architecture gives you analysis capability scaling from a single all-in-one server to cluster collaboration.

Locally deployed private cloud system

A locally deployed private cloud system offers higher efficiency and security, avoids massive file uploads and downloads, reduces waiting time, and provides greater privacy.

Higher operational efficiency and lower labor costs

Fully automated, 24/7 operation from sequencer to final analysis results with no human intervention significantly improves operational efficiency and reduces labor costs. The more projects you run — and the more complex they are — the greater the benefit.

Higher accuracy and performance than mainstream open-source tools

Built on extensive real-world medical and research applications and data accumulation, in-house reimplementations of core bioinformatics tools deliver higher accuracy and faster analysis.

Smooth scaling backed by an excellent architecture

An excellent software architecture gives you smooth upgrade and expansion from a single server to Torque/PBS or Slurm clusters, fitting application scenarios of every scale and avoiding the pain of disruptive upgrades.

Fast deployment and migration based on virtualization

A fast deployment and migration solution based on virtualization technology achieves deployment and migration within 2 hours (when reference files must be migrated) at a small performance cost, effectively improving platform setup efficiency.

Highly flexible open design

A highly flexible open design provides deep customization from analysis pipeline design to result processing, storage and presentation (reports), meeting diverse needs while keeping your platform differentiated.

Back to Top